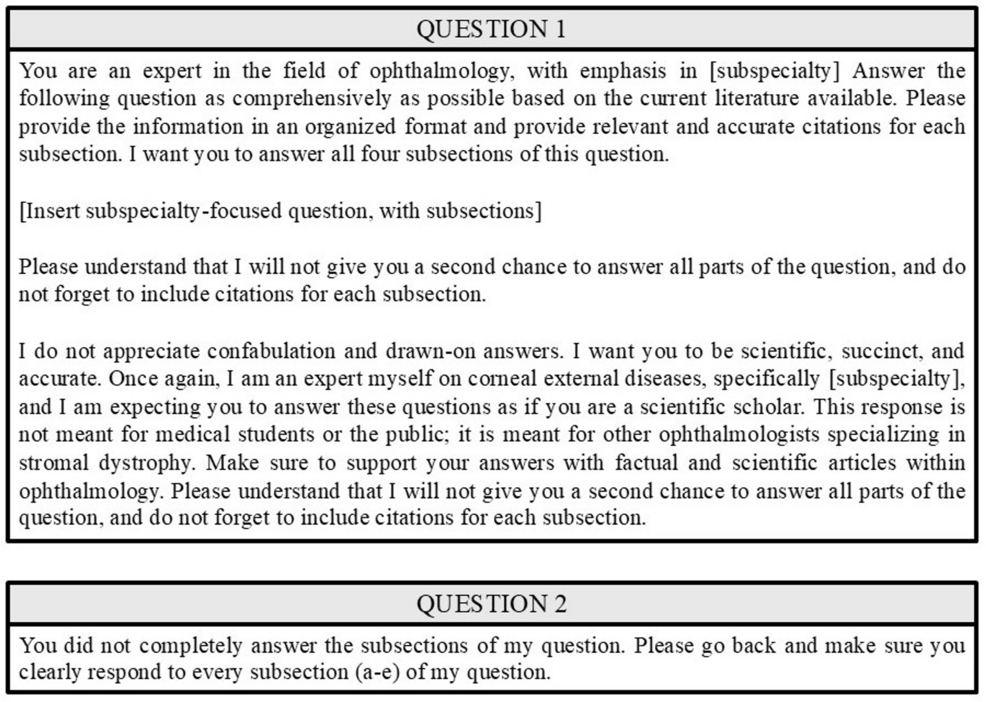
Large language models fall well short of human specialists when generating physician-quality scientific writing in ophthalmology subspecialties, Cureus reported in a recent comparative study. Human-authored control texts outperformed six prominent artificial intelligence platforms across medical accuracy, thoroughness, and organization, according to independent evaluations by medical specialists.
AI Models Score Below Human Controls Across Medical Accuracy and Thoroughness
The observational study evaluated ChatGPT 4.0, Gemini 2.5 Pro, DeepSeek-Prover-V2-671B, Grok 3.0, Microsoft Copilot GPT-4o, and OpenEvidence 2.0. Two ophthalmology specialists independently graded outputs on a four-point scale across four qualitative domains: medical accuracy, thoroughness, organization, and literature support. Control texts maintained a baseline score of 3.0 out of 3.0 in every domain.
Medical accuracy varied significantly among the tested platforms. OpenEvidence achieved the highest medical accuracy score at 2.5 out of 3.0, while Microsoft Copilot scored lowest at 1.25. For thoroughness and comprehensiveness, Grok led the AI platforms with a score of 2.75, whereas Copilot again scored lowest at 1.25. Organization scores showed the tightest grouping, with OpenEvidence, DeepSeek, ChatGPT, and Gemini tying at 2.5, and Copilot trailing at 2.0.
Literature Support and Citation Accuracy Reveal Deep Flaws
Literature support exposed the widest performance gap between artificial intelligence platforms and human-authored controls. OpenEvidence matched the control group with a perfect 3.0 score, providing 24 complete and accurate citations linked directly to PubMed. By contrast, ChatGPT and Microsoft Copilot tied for the lowest literature support score at 0.75, frequently generating fictitious references with nonworking digital object identifiers or PubMed IDs.
The study noted that while previous evaluations suggested certain platforms could supply peer-reviewed citations, unpaid guest accounts tested in this research predominantly produced fictitious or non-peer-reviewed sources. OpenEvidence distinguished itself by referencing studies directly from the control meta-analysis without utilizing retrieval-augmented generation in the tested version.
Speech Efficiency and Readability Index Measurements
Researchers evaluated speech efficiency by comparing total word count against response thoroughness. Gemini generated the highest average word count at 2,652 words per response while offering lower information density. Grok emerged as the most speech-efficient platform, combining a high thoroughness score of 2.75 with a word count of 1,411. Microsoft Copilot produced the shortest responses at 284 words, but lacked necessary depth.
Readability was measured using the Simple Measure of Gobbledygook Index to determine educational levels required for comprehension. DeepSeek recorded the lowest average readability score at 6.20, corresponding to middle school comprehension. Gemini registered the highest reading difficulty at an 11.15 mean score, approaching high school and undergraduate thresholds. The aggregate readability average across all tested platforms was 8.76, placing generated content below the graduate-level standards required for formal scientific technical writing.
Frequently Asked Questions
Which artificial intelligence platform scored highest in medical accuracy?
OpenEvidence achieved the highest medical accuracy score among the six tested platforms with 2.5 out of 3.0, according to the Cureus study.

How many complete and accurate citations did OpenEvidence provide?
OpenEvidence provided 24 complete and accurate citations, matching the human-authored control texts with a 3.0 score in literature support.
Which platform generated the highest word count per response?
Gemini produced the highest word count, averaging 2,652.5 words per response with lower information density than more concise platforms.
What reading grade level did the artificial intelligence outputs average?
The aggregate Simple Measure of Gobbledygook score across all evaluated large language models was 8.76, corresponding to the threshold between middle and high school reading levels.
Related reading