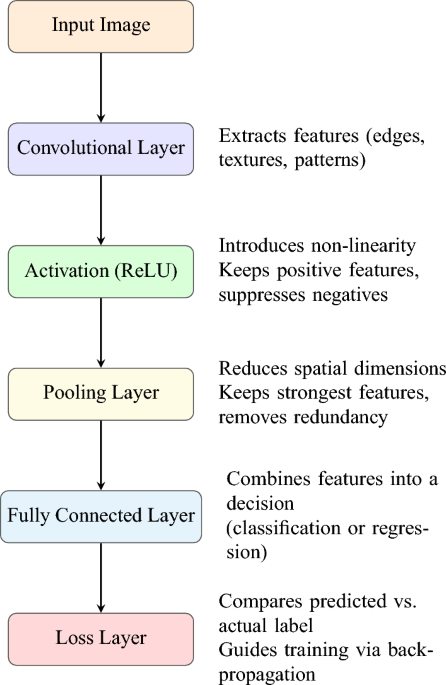
Deep learning architectures for traffic sign recognition achieved a 97.82% validation accuracy in a recent benchmarking study, according to research published in Scientific Reports on Saturday.
This performance exceeded the 94–96% accuracy range reported in previous baseline models.
The study, authored by Mona Hesham, Mohammed Abdrabou, Mahmoud A. Shawky, and Tamer ShamsEldin, evaluated several convolutional neural network (CNN) and transformer-based models using the German Traffic Sign Recognition Benchmark (GTSRB) dataset. Researchers utilized these models to address persistent challenges in autonomous driving, such as poor lighting, weather-related visibility issues, and obscured signage.
The research team contrasted classification-based models with detection-based frameworks to assess their utility for advanced driver assistance systems (ADAS). While classification models like AlexNet and Xception focus on identifying signs, the YOLOv11 framework provides spatial localization capabilities.
| Architecture | Validation Accuracy |
|---|---|
| Reproduced Custom CNN | 97.82% |
| VGG16 | not specified |
| AlexNet | 90.49% |
| Xception | 92.95% |
The VGG16 model, implemented via transfer learning, demonstrated notable instability during training. Although validation accuracy dipped to roughly 60% at the fourth epoch, the model ultimately converged to approximately 94%, surpassing the 90% peak previously documented in research by Chourasia et al.
Beyond traditional CNNs, the study introduced two transformer-based architectures: ViT-B/16 and DeiT-Tiny. These models use pretrained ImageNet weights to achieve high recognition rates with varying computational footprints.
DeiT-Tiny, which contains a relatively small number of parameters, proved particularly efficient for embedded deployment scenarios. Despite being roughly 15 times smaller than the 86-million-parameter ViT-B/16 model, DeiT-Tiny achieved a test accuracy of 96.61% and outperformed the larger model in precision, recall, and F1-score in this single-run comparison.
YOLOv11 was evaluated for its potential in real-time applications, requiring a conversion of the GTSRB dataset into normalized center-based coordinates. On a held-out test set of images, the model reached a mAP50 score of 97%.
The inference process for YOLOv11 measured 12.0ms per image at a 320×320 resolution, with an additional 2.4ms for preprocessing and 1.4ms for postprocessing. This speed highlights the model’s suitability for systems that prioritize rapid spatial localization alongside classification correctness.
Which evaluation metrics did the researchers prioritize?
The team utilized accuracy, precision, recall, and the F1-score to assess classification models. For the detection-based YOLOv11 framework, they primarily relied on mAP50 and mAP50-95 to account for both localization and classification performance.
How does Xception differ from standard CNN models?
Xception uses depthwise separable convolutions, which factorize standard operations into depthwise and pointwise components. This design significantly reduces the number of learnable parameters while maintaining high representational capacity for traffic sign features.
What remains unknown about these architectural comparisons?
The study notes that the reported performance margins—particularly the superior metrics of DeiT-Tiny over ViT-B/16—are based on a single-run comparison. Repeated trials with multiple random seeds would be required to confirm whether these performance advantages remain consistent across different training conditions.
Related reading